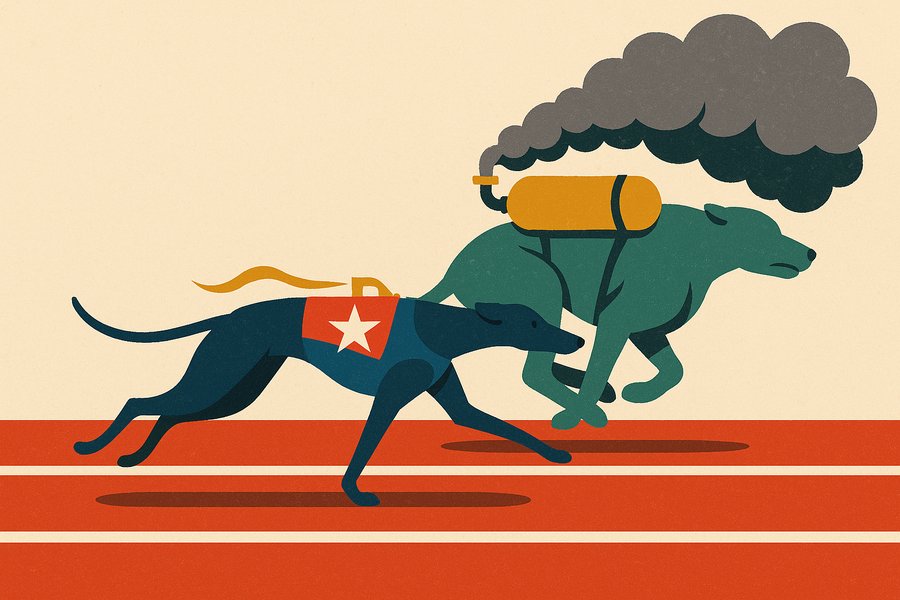
For two years the contest between American and Chinese AI labs has been framed as a race for raw intelligence: who can post the highest score on the hardest benchmark. Reflection AI, the Brooklyn startup backed by Nvidia, has just launched a model that quietly changes the question. Its first frontier model, Beam, unveiled on 5 October, does not claim to be the smartest open model in the world. It claims to be nearly as smart as China's best while costing a fraction as much to run. That is a different kind of bet, and a more revealing one about where the industry's real anxieties now lie.
The headline numbers are striking. Beam is a sparse mixture-of-experts model with 501 billion total parameters but only 23 billion active at any moment, the design choice that lets a very large model behave like a much smaller one at inference time. Reflection trained it on 23.8 trillion tokens using 6,144 Nvidia GB300 chips, finishing the pretraining run in under four weeks. On the company's own figures it scores 80.9 on the SWE-Bench Verified coding test, 80.1 on Terminal-Bench, and 97.8 on this year's AIME maths exam, roughly level with GLM-5.2, the flagship open model that Beijing-based Z.ai released in June. Reflection is careful not to say it beat the Chinese model. It says it matched it, then did so using three to four times less compute.
That efficiency claim, not the benchmark score, is the whole pitch, and the company knows it. Beating a public leaderboard is no longer the hard part: DeepSeek and Alibaba's Qwen have proved that Chinese labs can hit frontier-adjacent scores and give the weights away. The fight has moved to what it costs to serve those scores to millions of users every day. Every point of reasoning quality Beam can hold while spending a quarter of the tokens is a point of margin for whoever runs it, which is why the audience Reflection cares about is not researchers admiring a chart but the hyperscalers and governments deciding which open model to standardise on.
Reflection frames itself explicitly as the American answer to DeepSeek and Qwen, not as a challenger to closed labs like OpenAI or Anthropic. That positioning explains Nvidia's interest. Nvidia does not need another model to sell chips, but it does need the market for open-weight models to stay competitive enough that enterprises keep buying GPUs to run models themselves rather than renting inference from a handful of closed providers. A credible US open lab serves that goal directly, which is part of why Nvidia wrote an $800 million cheque in Reflection's last round. The company, founded in March 2024 by two former Google DeepMind researchers, has raised roughly $4.7 billion and was recently in talks at a $25 billion valuation, a dizzying climb for a firm shipping its first model.
The large caveat sits underneath all of it: none of these figures has been independently verified. Reflection is releasing an early version through a waitlist while it finishes red-teaming, with full weights under a permissive Apache 2.0 licence promised "later this month." Until an outside researcher can load a public checkpoint and rerun the tests, the three-to-four-times efficiency claim is a marketing number, not a measured one. Reflection has lined up the customers an open strategy is built to win, from a certification in the US Department of Energy's Genesis Mission to a 250-megawatt sovereign AI cloud in South Korea. Whether they standardise on Beam depends on a single question that the launch pointedly leaves open: does the cheapness survive contact with everyone else's hardware?